AI News Today

Follow AI model releases, new AI tools, and product updates. See what's new, what's changed, and which features are now available.

Trending AI News

What readers are reading right now · Updated Sep 24, 2026, 01:51 PM

Top01
Abstract glowing model tiers representing the GPT-6 family
Models

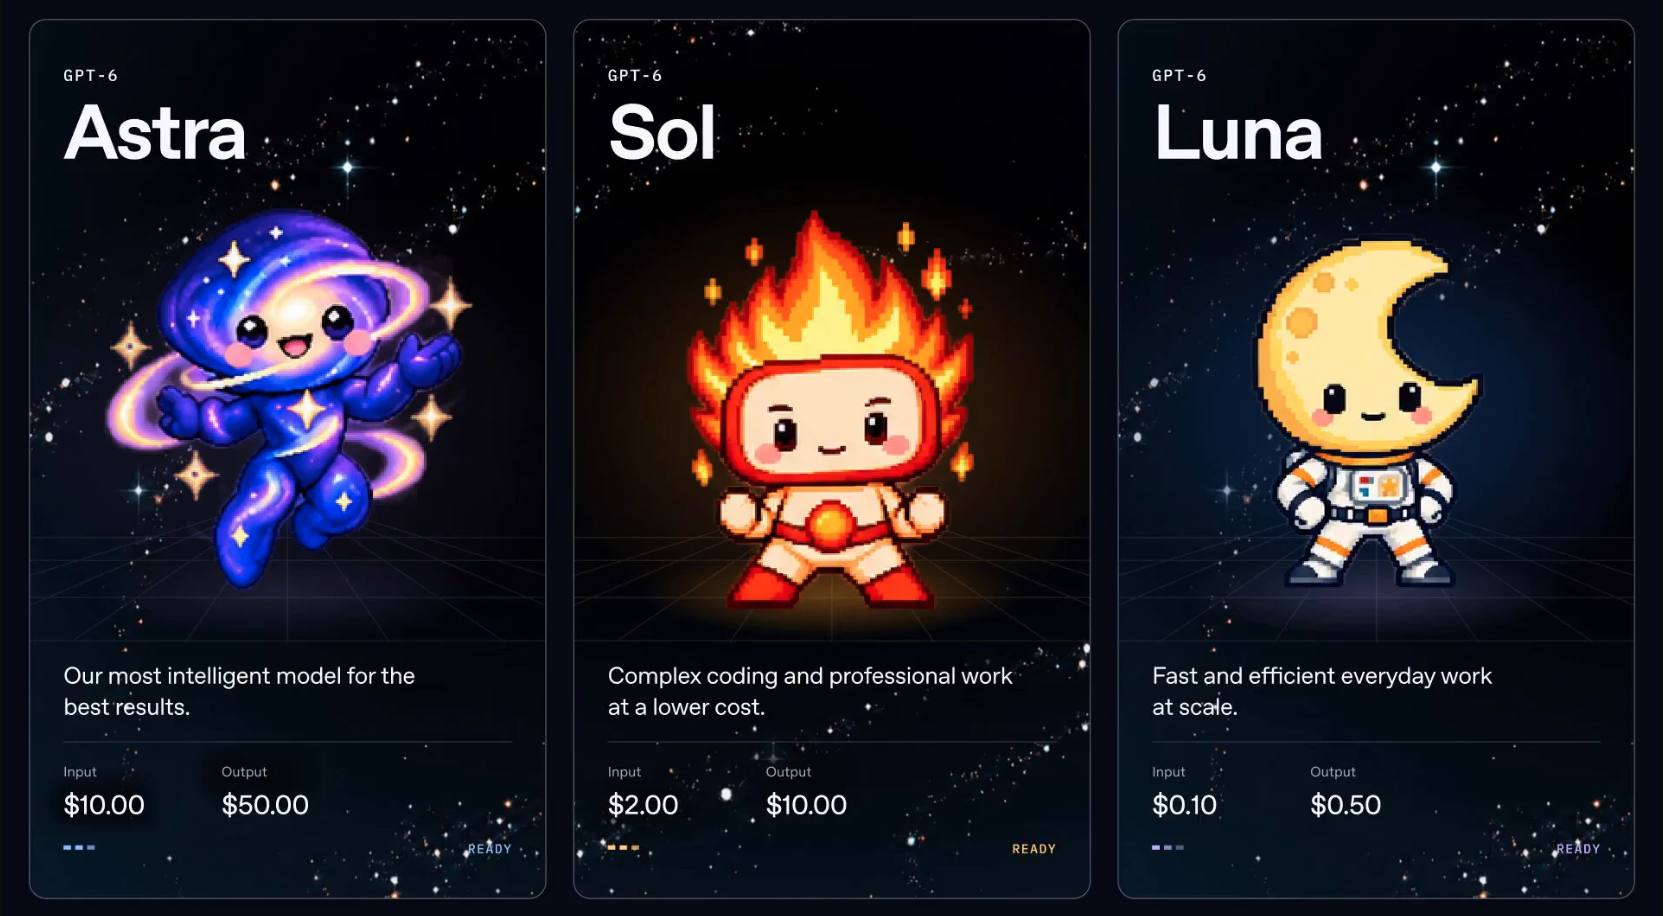
GPT-6 Sol and Luna Explained: Astra, Sol, Luna, and the API Price Cut

OpenAI's GPT-6 line now has three models: Astra for flagship work, Sol for coding and analysis at $2/$10, and Luna for high-volume tasks at $0.10/$0.50. We break down what each one is for, the benchmarks OpenAI published, and what the half-price API cut means for everyday users and developers.

Heat: 1,350
Top02
GPT-6 Sol and GPT-6 Luna compared side by side
Comparisons

GPT-6 Sol vs Luna: Where the 20x Price Gap Actually Shows Up

GPT-6 Sol costs 20x more per token than Luna, but the benchmark scores land within two points on DeepSWE. We compare the pricing, the AutomationBench and DeepSWE results, and the cost-per-task math to show which workloads need the expensive model and which are wasting money on it.

Heat: 1,200
Top03
Grok 4.7, xAI's new model release
Models

Grok 4.7 Is Out: Same $2/$6 Price, a Bigger Base Model, and a 500K Context

xAI released Grok 4.7 on September 21 at the same $2/$6 pricing as Grok 4.6, built on a larger base model with longer reinforcement learning for long-horizon tasks. It nearly doubles its Terminal-Bench score but still trails Fable 5.1 on several tests, and it burns far more tokens per task.

Heat: 1,150
Top04
Grok 4.7 compared with Grok 4.6
Comparisons

Grok 4.7 vs Grok 4.6: What the Benchmark Jumps Actually Mean

Grok 4.7 keeps the same $2/$6 price as Grok 4.6 but rewrites the base model. Terminal-Bench nearly doubles, hallucinations drop from 34% to 29%, and accuracy stays flat. We compare the vendor table against independent testing, including the token usage that can offset the flat price.

Heat: 1,000

Latest AI News

All the latest AI stories, in chronological order.

2026-09-24

4 Stories
Grok 4.7 compared with Grok 4.6
Comparisons

Grok 4.7 vs Grok 4.6: What the Benchmark Jumps Actually Mean

Grok 4.7 keeps the same $2/$6 price as Grok 4.6 but rewrites the base model. Terminal-Bench nearly doubles, hallucinations drop from 34% to 29%, and accuracy stays flat. We compare the vendor table against independent testing, including the token usage that can offset the flat price.

Heat: 1,000
Read Story
Grok 4.7, xAI's new model release
Models

Grok 4.7 Is Out: Same $2/$6 Price, a Bigger Base Model, and a 500K Context

xAI released Grok 4.7 on September 21 at the same $2/$6 pricing as Grok 4.6, built on a larger base model with longer reinforcement learning for long-horizon tasks. It nearly doubles its Terminal-Bench score but still trails Fable 5.1 on several tests, and it burns far more tokens per task.

Heat: 1,150
Read Story
GPT-6 Sol and GPT-6 Luna compared side by side
Comparisons

GPT-6 Sol vs Luna: Where the 20x Price Gap Actually Shows Up

GPT-6 Sol costs 20x more per token than Luna, but the benchmark scores land within two points on DeepSWE. We compare the pricing, the AutomationBench and DeepSWE results, and the cost-per-task math to show which workloads need the expensive model and which are wasting money on it.

Heat: 1,200
Read Story
Abstract glowing model tiers representing the GPT-6 family
Models

GPT-6 Sol and Luna Explained: Astra, Sol, Luna, and the API Price Cut

OpenAI's GPT-6 line now has three models: Astra for flagship work, Sol for coding and analysis at $2/$10, and Luna for high-volume tasks at $0.10/$0.50. We break down what each one is for, the benchmarks OpenAI published, and what the half-price API cut means for everyday users and developers.

Heat: 1,350
Read Story