
apiJuice
Shashwat (independent maker) · Coding
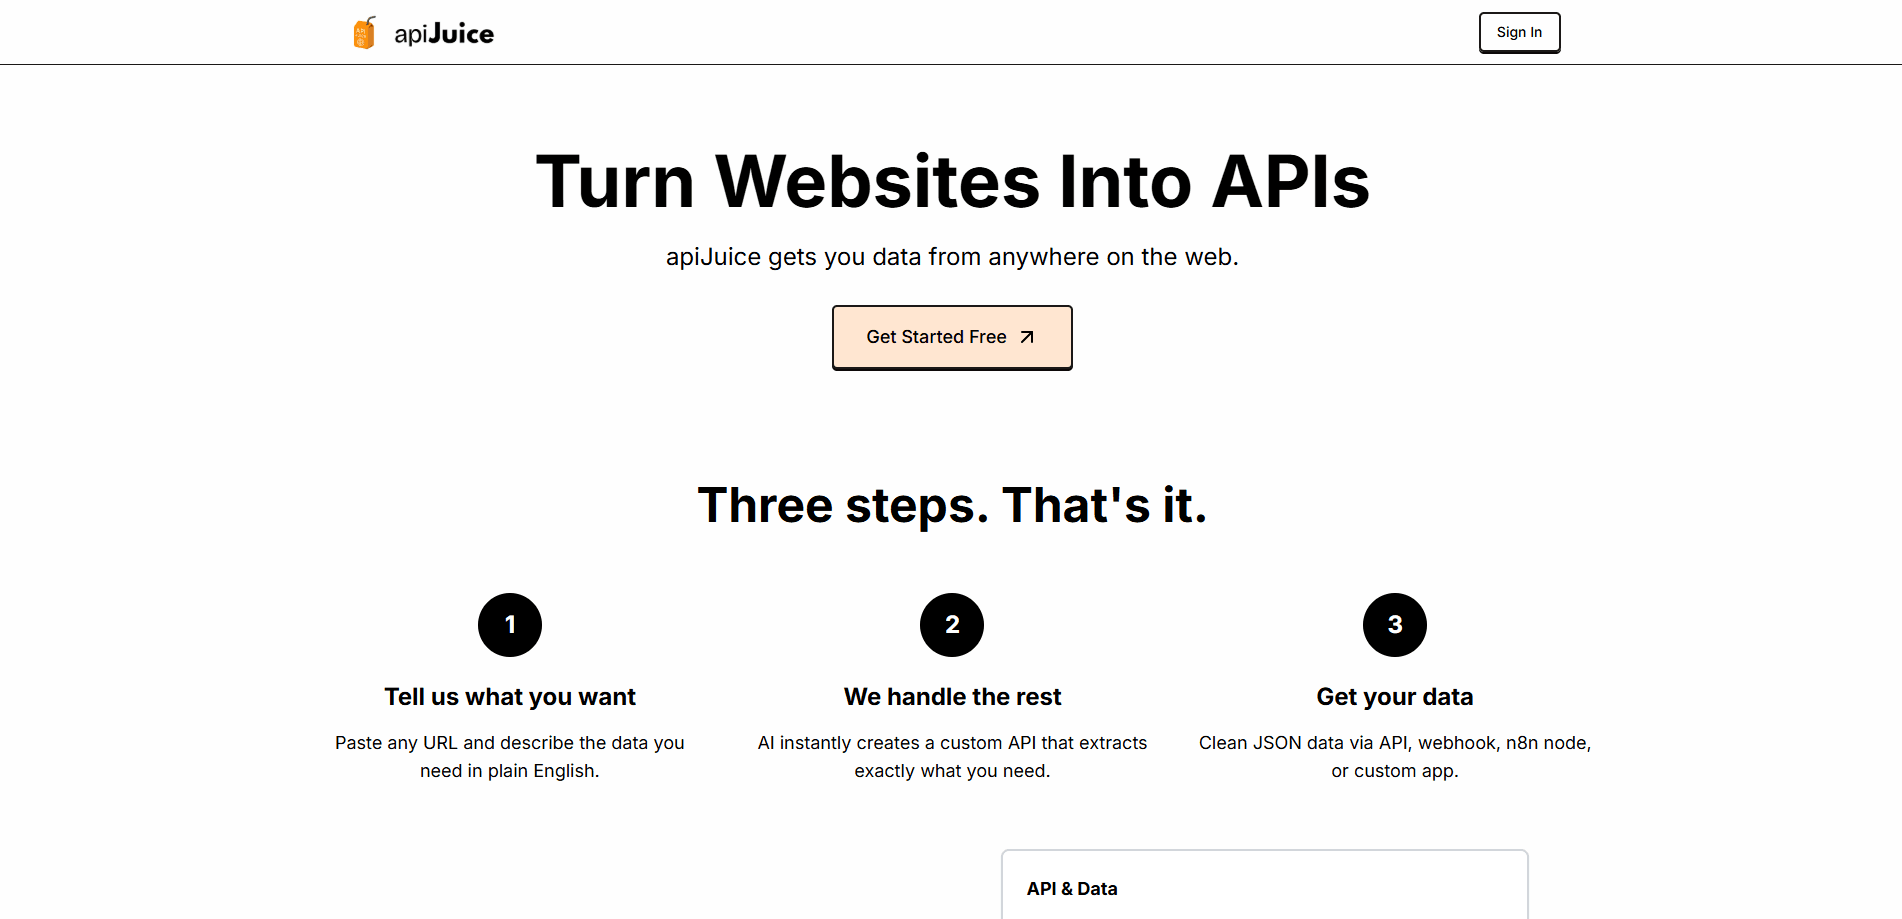
apiJuice turns any website into a hosted API. You paste a URL, describe the data you want in plain English, and it returns clean JSON that your apps and workflows can call.
About apiJuice
What Is apiJuice
apiJuice is a web scraping API that builds custom endpoints from ordinary web pages. Instead of writing a scraper from scratch, you point it at a URL and say what you need, like product prices, article titles, or job listings. The platform reads the page with AI and hands back a structured endpoint that anyone on your team can call.
The tool targets a common headache: getting data out of sites that were never meant to share it. Traditional scrapers break whenever a site tweaks its layout, and each fix costs developer time. apiJuice keeps the extractor logic on its side and updates it as pages change, so you spend less effort on maintenance.
There are real limits to keep in mind. apiJuice works with JSON data extraction on public pages it can reach, not behind login walls or heavy anti-bot defenses. Every request runs against a credit budget on the free tier, and results depend on how clearly you describe the fields you want.
Getting Started
- Sign up at apijuice.com with your email or a Google account to get a starting balance of credits.
- Paste the URL of the page you want to turn into an API.
- Describe the data to extract in plain English, for example "all product names, prices, and ratings," then let the AI build the JSON structure.
- Review the generated structure, adjust the fields if needed, and save the endpoint.
- Copy your API key and call the endpoint over HTTP, or export it as a webhook, n8n node, or custom app.
Product Information
A quick look at apiJuice's pricing, supported platforms, and performance.
Best for
The users, tasks, and scenarios where this tool fits best.
Users
- Solo developers
- No-code builders
- Small operations teams
Tasks
- Pulling product prices and stock levels
- Collecting article or post metadata
- Feeding automation workflows
Scenarios
- Prototyping an idea fast
- Monitoring a competitor's catalog
- Enriching an internal tool
Key features
Instant API from a URL
The core move is simple. Paste a link, describe the fields you want, and apiJuice returns a hosted endpoint that responds with JSON. There's no server to set up and no scraping library to install, which cuts a task that usually takes hours down to minutes.
Plain-English Data Requests
You don't write selectors, XPath, or regex. You describe what you need in everyday language, and the AI maps that request onto the page's structure. This lowers the barrier for people who understand the data they want but not the front-end code behind it.
Self-Healing Extractors
Sites change their layouts, and most scrapers break when they do. apiJuice keeps the extraction logic on its side and lets you describe a fix in words when something stops working, so the AI updates the extractor instead of you rewriting it.
Flexible Delivery Options
Each saved endpoint can be called in more than one way. You get an HTTP API with a Bearer key, a webhook, an n8n node you can import, or a generated custom app. That range means the same endpoint fits a developer's script and a non-technical teammate's workflow.
Custom Apps for Viewing Data
Beyond raw JSON, apiJuice can generate a small web app that displays your data with a refresh button and a clean interface. You can share it with teammates or embed it, and no API key is needed to view it.
Scheduled and On-Demand Runs
You can set endpoints to update on a schedule or pull fresh data whenever you need it. That keeps a monitoring job or a dashboard fed without anyone remembering to trigger it by hand.
Speed Without a Browser
The service skips the overhead of running a full browser for every request. It focuses on extracting the data itself, which keeps response times short and makes frequent polling practical.
Pros and cons
Pros
- Setup takes minutes, not hours, because you describe data in plain English instead of writing selectors.
- One endpoint can be consumed as an HTTP API, webhook, n8n node, or custom app, so it fits both technical and non-technical users.
- Extractors are maintained on the service side, which reduces the breakage that plagues hand-built scrapers.
- A free starting credit balance lets you test the workflow before paying.
Cons
- The free tier runs on a credit budget, so heavy or frequent jobs will push you toward a paid plan.
- It depends on pages being publicly reachable, so gated content and aggressive anti-bot sites won't work.
- Output quality tracks how clearly you describe the fields you want, so vague requests can return messy data.
Frequently asked questions
It turns a web page into a hosted API. You give it a URL and a description of the data you need, and it returns a JSON endpoint your apps or automations can call.
Related content
Explore related tools, skills, and articles for apiJuice.
apiJuice Alternatives

Base Code
Base44 (Wix) · Coding · ProductivityBase Code is a shared cloud development environment from Base44. Teammates describe changes to an existing GitHub codebase in chat, preview them live and send them back as pull requests.

Google EmbeddingGemma 2
Google DeepMind · Writing · Image · CodingGoogle EmbeddingGemma 2 is a 740M-parameter open model that turns text, code, images, audio, and video frames into vectors in one 768-dimension space, running on phones and laptops.

GitGlow
GitGlow · Coding · ProductivityGitGlow is a local-first desktop Git client that lets independent developers review their own code and their AI agents' changes in one place before shipping.