
Awan LLM
Awan LLM · Coding · Other
Awan LLM is a subscription API for Llama models that charges a flat monthly fee instead of per token, with an OpenAI-style endpoint and plans from free to $80/mo.
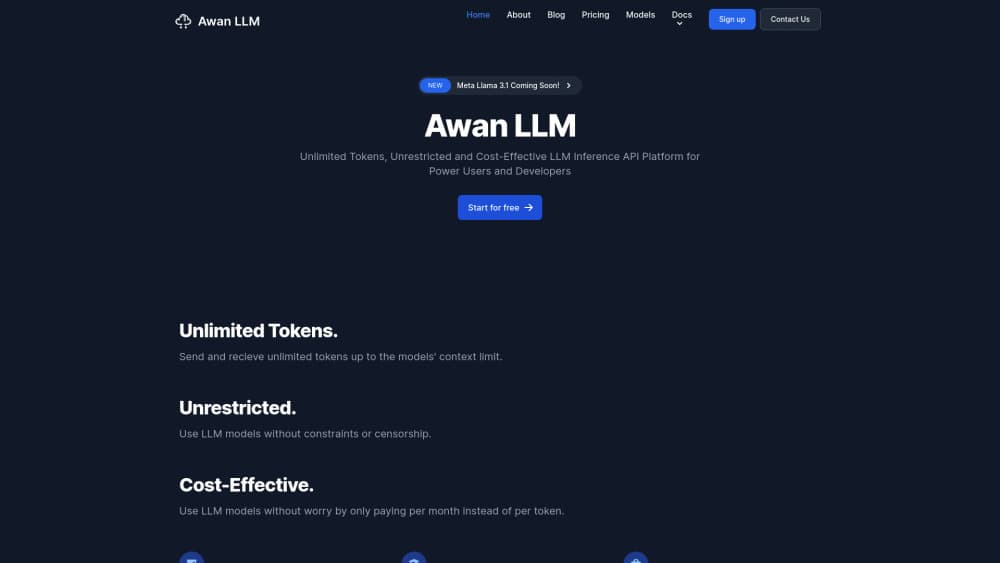
About Awan LLM
What Is Awan LLM
Awan LLM is an inference API that rents access to open Llama models by the month rather than by the token. You sign up, get an API key, and send requests to a chat completions endpoint that mirrors the OpenAI request shape. The bill stays the same whether you push a thousand tokens or a hundred million.
The company runs the hardware itself. Awan says it owns its GPUs and datacenters, overclocks them, and balances load across them, and that ownership is the reason it can promise unlimited tokens at $5 to $80 a month. The name comes from the Indonesian word for cloud, and the pitch is aimed at people whose token bill has outgrown their project.
Two limits decide whether it fits. The public catalog is Llama 3 and Llama 3.1 in 8B and 70B sizes, including community fine-tunes, with no GPT, Claude, Gemini, or Mistral options. And requests are capped per minute and per day by plan and model class, so unlimited tokens doesn't mean unlimited requests.
Getting Started
- Create an account at awanllm.com and pick a plan. Lite is free and needs no card, which is enough to test whether the endpoint behaves the way your code expects.
- Generate an API key in the dashboard and store it where your app can read it.
- Send your first request to https://api.awanllm.com/v1/chat/completions with a model name and a messages array, using the Python, TypeScript, or shell sample on the Quick Start page.
- Watch the rate limits. If you hit the daily cap on large models, move work to a smaller model or wait for the counter to reset.
- Move to a paid plan when the request caps start to bite, not when the token count does.
Product Information
A quick look at Awan LLM's pricing, supported platforms, and performance.
Best for
The users, tasks, and scenarios where this tool fits best.
Users
- Hobbyists running long conversations with an AI companion
- Indie developers building a prototype on a tight budget
- Writers and roleplayers using fine-tuned models
- Teams processing large volumes of text on a fixed cost
Tasks
- Bulk text processing
- Long-form drafting
- Chatbot and agent backends
- Uncensored creative writing
Scenarios
- A side project that suddenly gets traffic
- Testing a prompt library
- Running dev tooling against a remote model
Key features
Unlimited Tokens on a Flat Monthly Fee
Every plan, including the free one, advertises unlimited token generation up to each model's context limit, which is the whole premise of the product as an unlimited token LLM API. You pay for the plan, not for input or output tokens, so a long prompt or a long answer costs nothing extra. That flips the usual economics: heavy use makes the deal better, and a busy month never produces a surprise invoice.
OpenAI-Style Chat Completions
Requests go to https://api.awanllm.com/v1/chat/completions with the same model and messages fields OpenAI uses, plus extra sampling controls such as top_k and repetition_penalty. Python, TypeScript, and shell examples sit on the Quick Start page, so most OpenAI SDKs work once you swap the base URL and key. Streaming is supported, which matters for chat interfaces where waiting on a full answer feels broken.
Rate Limits Split by Model Size
Instead of one global quota, Awan splits its rate limits into small, medium, and large model classes and gives each plan a per-minute and a per-day allowance. Lite allows 200 small model requests a day and 10 large ones; Pro raises that to 80,000 and 30,000; Max drops the daily cap and adds parallel requests. The per-minute ceiling runs from 20 on the cheaper plans to 200 on Max.
Llama 3.1 With Long Context
The current flagship entries in the Llama 3.1 API are Meta-Llama-3.1-8B-Instruct and Meta-Llama-3.1-70B-Instruct, both listed with a 131,072-token context window. The 70B model takes the harder reasoning and writing work, while the 8B models answer faster and cost less of your request budget. Awan publishes estimated throughput per model, around 50 tokens per second for single requests on the 8B and 20 on the 70B.
Community Fine-Tunes for Creative Work
Past the stock Meta weights, the catalog lists Awan's own Llama 3 8B builds. Dolfin is tuned for exact instruction following with fewer refusals, Cumulus for storytelling and roleplay with no refusal behavior, and an abliterated Instruct build sits beside them. These are the uncensored Llama models in the lineup, narrow tools that behave very differently from a filtered assistant once you write fiction or run a character.
No Prompt Logging
Awan says in its privacy policy that it doesn't log prompts or generations, and repeats the claim on its homepage. For anyone sending client material, unpublished drafts, or personal conversations through an API, that policy often decides the purchase. Treat it as a stated policy rather than an audited guarantee, so regulated workloads still need their own review.
Pros and cons
Pros
- Unlimited tokens takes token counting out of your code and your budget.
- The free Lite plan is a real tier rather than a trial, and it needs no payment method.
- Requests follow the OpenAI chat format, so existing SDKs and agent frameworks work with a base URL swap.
- The 131,072-token context on Llama 3.1 handles long documents in a single request.
- Plans top out at $80 a month, which is low for anyone pushing serious volume.
Cons
- The catalog is Llama only, and the listed versions are Llama 3 and 3.1, so you can't reach GPT, Claude, Gemini, or newer Llama releases here.
- Unlimited tokens still runs into per-day request caps on every plan below Max, so throughput rather than tokens becomes the wall.
- Payments run through PayPal only, which locks out some cards and business accounts.
- Support is an email address, with no status page, SLA, or public uptime record before the Enterprise plan.
Frequently asked questions
Awan LLM is an API provider that serves open Llama models on a monthly subscription instead of per-token billing. You pay for a plan, send chat completion requests to its endpoint, and generate as many tokens as the model's context allows within your request limits.
Related content
Explore related tools, skills, and articles for Awan LLM.
Awan LLM Alternatives

Base Code
Base44 (Wix) · Coding · ProductivityBase Code is a shared cloud development environment from Base44. Teammates describe changes to an existing GitHub codebase in chat, preview them live and send them back as pull requests.

Google EmbeddingGemma 2
Google DeepMind · Writing · Image · CodingGoogle EmbeddingGemma 2 is a 740M-parameter open model that turns text, code, images, audio, and video frames into vectors in one 768-dimension space, running on phones and laptops.

GitGlow
GitGlow · Coding · ProductivityGitGlow is a local-first desktop Git client that lets independent developers review their own code and their AI agents' changes in one place before shipping.