

LLMWare.ai
LLMWare.ai · Coding · Other
LLMWare.ai builds Model HQ, a no-code platform for running private AI workflows on your own hardware with 250+ small language models, on-device RAG and zero token costs.
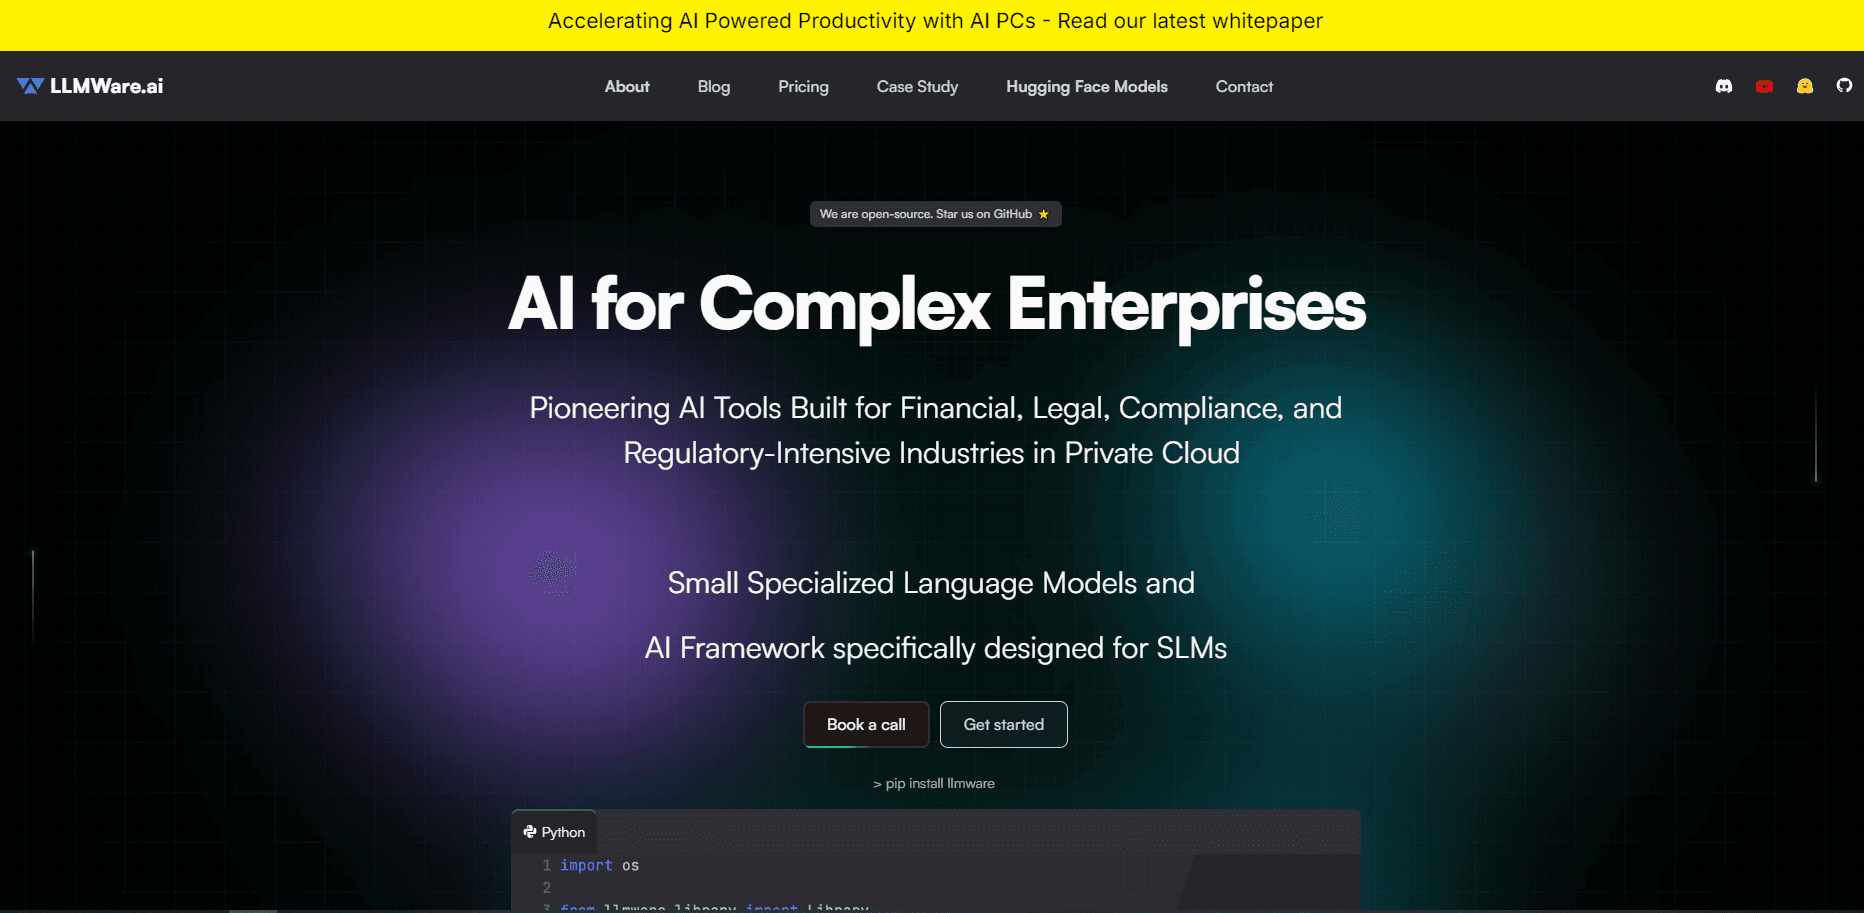
About LLMWare.ai
What Is LLMWare.ai
LLMWare.ai is the company behind Model HQ, a private AI workflow engine that runs language models on your own laptop, AI PC or data center instead of in someone else's cloud. It grew out of the open source llmware framework, a Python library for building retrieval-augmented generation (RAG) apps with small specialized models. The same team now ships both: the code framework for developers and Model HQ as the point-and-click product for everyone else.
The argument for going local is straightforward. Sensitive documents stay inside your security zone, there are no per-token charges, and the system works without a network connection for most workflows. That fits financial, legal, insurance and compliance teams, where sending contracts or client records to a public API is a non-starter. The company's framing is blunt: own your AI, keep the data where it lives.
The tradeoff is that local models are smaller. Model HQ runs models up to 32B parameters on current AI PCs, which is enough for document work, classification and structured extraction, but not the same ceiling as the largest cloud frontier models. You also install a client agent rather than signing into a web app, and the deepest deployment options are sold through enterprise conversations.
Getting Started
- Download the Model HQ client agent, around 200 MB, onto your AI PC or laptop
- Launch it and pick a model from the catalog of 250+ small language models
- Point it at your files or connect a data source to build an on-device knowledge base
- Chain models, data and logic into a workflow, then run it on demand or on a schedule
Product Information
A quick look at LLMWare.ai's pricing, supported platforms, and performance.
Best for
The users, tasks, and scenarios where this tool fits best.
Users
- Regulated-industry teams
- Security and IT leads
- Developers building RAG apps
- Small and mid-sized teams
Tasks
- Document processing
- On-device document search
- Structured data extraction
- IT and service workflows
- Scheduled automation
Scenarios
- Law or finance review
- Air-gapped or low-connectivity sites
- AI PC rollout
- Sensitive HR or medical files
- Prototyping before scale
Key features
No-Code Workflow Builder
Model HQ lets you build multi-step AI workflows without writing code. You chain models, data sources and logic into a repeatable process, from a simple summarize step to a multi-stage pipeline that reads a document, extracts fields and routes a result. That moves the product past a chatbot. It runs business tasks end to end, and the company positions the no-code builder as the piece that opens AI automation to people who never touch Python.
250+ Small Language Models
The platform ships a catalog of more than 250 small language models, prepackaged in quantized formats so they run on device GPUs and NPUs. It lists the SLIM family (Structured Language Instruction Models) for function calling and classification, the DRAGON models tuned for RAG question answering, and BLING models for quick prototypes. It also supports leading cloud models from OpenAI, Anthropic and Google, so you mix local and cloud where each makes sense.
On-Device RAG and Document Search
Model HQ includes a built-in retrieval-augmented generation pipeline, the same technology behind the open source llmware framework. You point it at a folder of PDFs, Word documents or spreadsheets; it parses, chunks and indexes the files, then answers questions using that context. The company connects it to a range of vector databases, including FAISS, Milvus, Pinecone, Qdrant, Postgres (PG Vector), Redis and Chroma, for teams that already run one.
Runs on AI PC Hardware
The client agent is built to use the silicon already on a modern laptop. It runs across CPUs, GPUs and NPUs, and is optimized for chips from Intel, AMD, Apple, NVIDIA and Qualcomm Snapdragon. The company cites average download times of around 10 seconds for the app and under 30 minutes for a set of models onto a device. Models up to 32B parameters run on the latest AI PCs, so you get useful capability without a server.
Zero Token Cost and No Cloud Dependency
Because inference runs on your own hardware, there are no per-token charges and no metered API bill. The company puts the expected incremental per-token cost on an AI PC at $0. Most workflows run without a network connection, which matters for field teams, secure facilities and anyone who would rather not depend on an outside service being up. Your data stays in your environment by default.
Private Deployment Options
Model HQ is designed to run in three places: on AI PCs, in your data center for batch inference and RAG over sensitive data, or in a private cloud for time-sensitive and large operations. The three can link together for a mixed setup, so a laptop agent pulls from a central deployment when it needs bigger models. Enterprises can build AI agent apps and deploy them to staff devices across the organization.
Enterprise AI Safety Tooling
The platform bundles the controls a regulated buyer asks for. It includes AI explainability, PII filtering, toxicity and bias monitoring, and hallucination detection. Enterprise deployments add monitoring, updates and scaling across mixed hardware. Combined with on-device execution, that gives compliance teams a way to answer where the data went and what the model saw.
Pros and cons
Pros
- Runs locally, so sensitive documents never leave your security zone and there are no per-token fees
- No-code builder lets you assemble no-code AI agents and multi-step workflows without development skills
- Supports both small local models and major cloud models, so you can mix where each fits
- Ships a large catalog of specialized models for RAG, classification and function calling
- Deploys across AI PCs, data centers and private cloud from one platform, with a free starting tier
Cons
- Local models cap out around 32B parameters, so the hardest reasoning tasks still favor large cloud models
- You install and manage a client agent, which takes more setup than opening a web app
- Full data center and private cloud deployment is sold through enterprise conversations, so pricing is not public
- Most workflows run well without a network, but the largest models and cloud integrations still need connectivity
Frequently asked questions
LLMWare.ai is an AI company that builds Model HQ, a private AI workflow engine for running language models on your own hardware. It also maintains the open source llmware Python framework for building RAG applications. The company focuses on data-sensitive industries like financial services, legal and insurance.
Related content
Explore related tools, skills, and articles for LLMWare.ai.
LLMWare.ai Alternatives

Base Code
Base44 (Wix) · Coding · ProductivityBase Code is a shared cloud development environment from Base44. Teammates describe changes to an existing GitHub codebase in chat, preview them live and send them back as pull requests.

Google EmbeddingGemma 2
Google DeepMind · Writing · Image · CodingGoogle EmbeddingGemma 2 is a 740M-parameter open model that turns text, code, images, audio, and video frames into vectors in one 768-dimension space, running on phones and laptops.

GitGlow
GitGlow · Coding · ProductivityGitGlow is a local-first desktop Git client that lets independent developers review their own code and their AI agents' changes in one place before shipping.