
Orpheus TTS
Canopy Labs · Voice & Language
Orpheus TTS is an open source text to speech model from Canopy Labs, built on a Llama 3B backbone, that clones voices zero-shot, adds emotion tags, and streams audio with low latency.
About Orpheus TTS
What Is Orpheus TTS
Orpheus TTS is an open source text to speech model from Canopy Labs. It runs on a Llama 3B backbone, which means the team applies large language model techniques to speech synthesis instead of a traditional acoustic pipeline. The result is speech that carries natural rhythm, intonation, and emotion, and the project publishes its code and model weights so anyone can run it.
The idea behind it is simple. Older speech systems handled each stage, text parsing, timing, and audio generation, with separate components. Orpheus treats the problem as a generation task an LLM already knows how to handle. The model learned to produce speech tokens the same way a language model produces words, and that framing led to emergent behavior the authors say matches or beats some closed source options.
What you get is a tool for developers, not a finished app. There is no single website where you type a sentence and download a file. You install the package, host the model, and wire it into your own product. That flexibility matters if you want voice output without a per-request bill, and it also means you handle the hardware and the setup yourself.
Getting Started
- Clone the repository or install the package with pip install orpheus-speech, which uses vllm under the hood for fast inference.
- Load a model such as canopylabs/orpheus-tts-0.1-finetune-prod through the OrpheusModel class.
- Write your text with an optional speaker name and emotion tags, then call generate_speech with a voice from the supported list.
- Stream the returned audio chunks into a WAV file or straight into your app for realtime playback.
- For your own voice, prepare a Hugging Face dataset and run the fine-tuning scripts, aiming for roughly 300 examples per speaker.
Product Information
A quick look at Orpheus TTS's pricing, supported platforms, and performance.
Best for
The users, tasks, and scenarios where this tool fits best.
Users
- Developers adding voice to an app
- Creators who want a specific voice
- Builders working on realtime conversation
Tasks
- Cloning a voice from a short sample
- Adding emotion to narration
- Generating speech across languages
- Running speech locally for privacy
Scenarios
- Powering a voice assistant loop
- Narrating audiobooks and long scripts
- Dubbing video into another language
Key features
Human-Like Speech
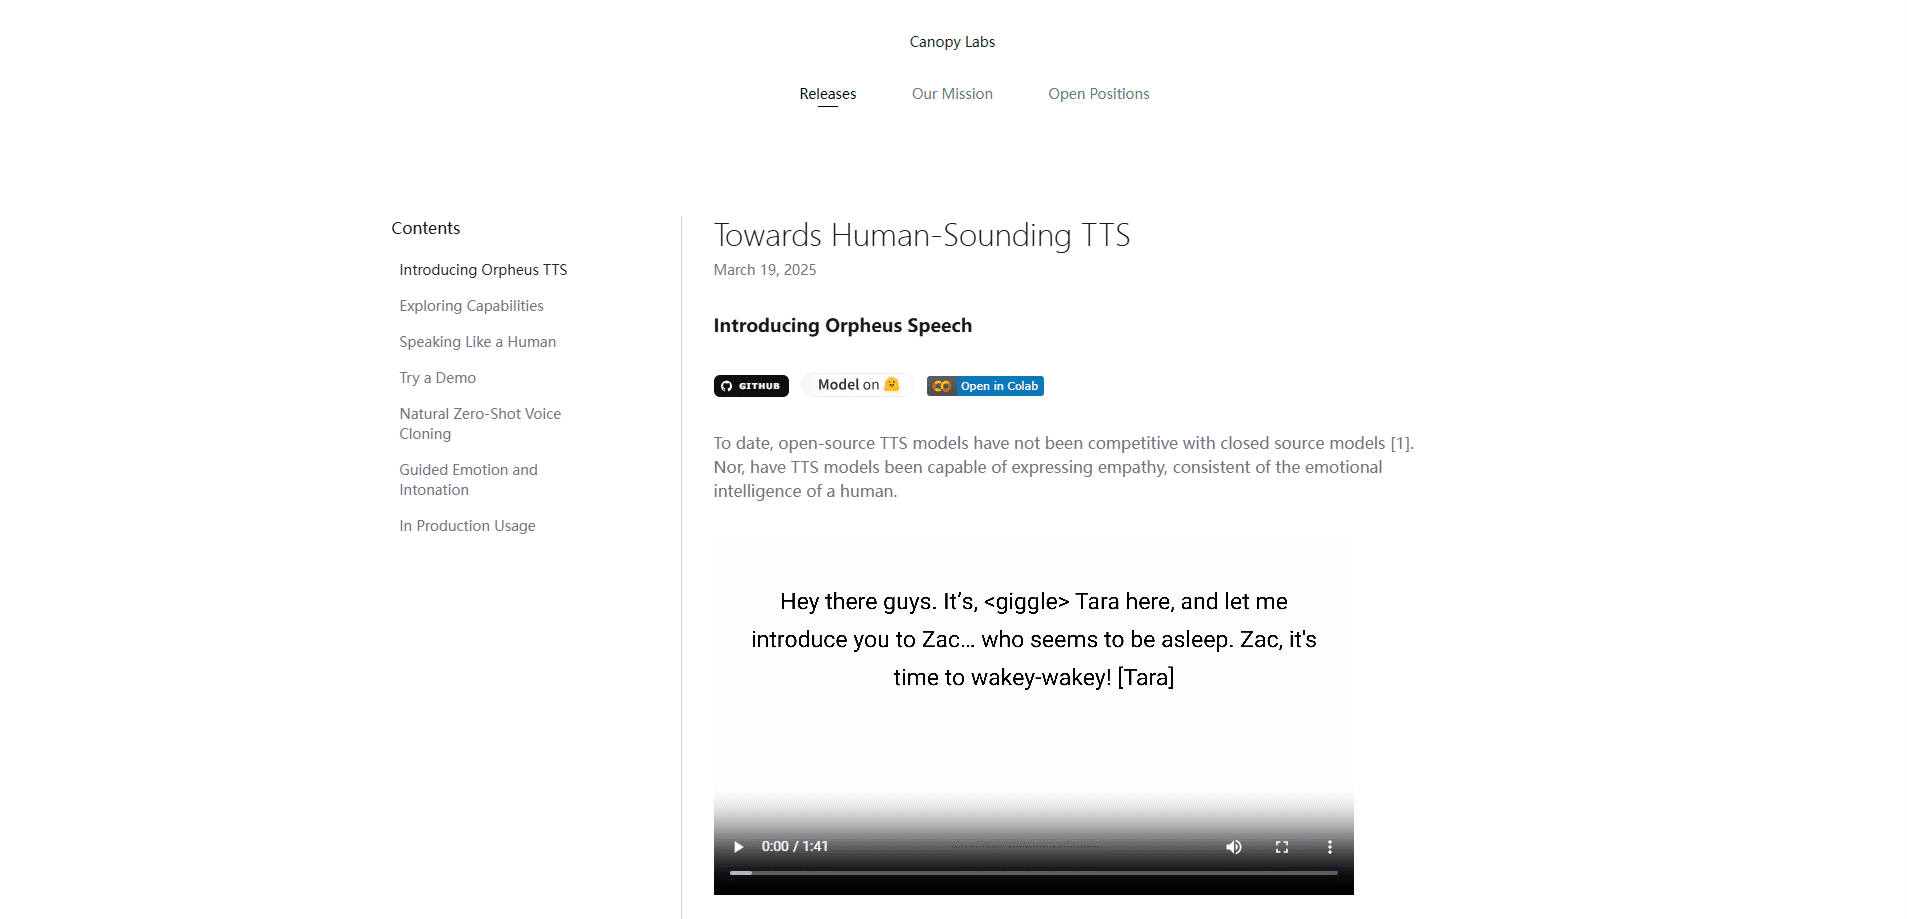
Orpheus TTS produces intonation, emotion, and rhythm that the authors say rivals or beats top closed source systems. It picks up cues in the text and can drop in a sigh or a laugh where the writing suggests it. This is the headline claim, and it's what pushed the project into the open source conversation. Clean text with clear cues gets the best results.
Zero-Shot Voice Cloning
The pretrained model can copy a voice without any fine-tuning. Give it one or more text-speech pairs in the prompt, and it imitates the speaker on fresh text. The more pairs you pass, the more reliably it lands on the right voice. This is what separates it from older systems that needed hours of recordings.
Guided Emotion and Intonation
You steer delivery with simple tags, including laugh, chuckle, sigh, cough, sniffle, groan, yawn, and gasp. The model reads these as part of the text and shapes the audio around them. For dialogue, audiobooks, or a chatbot that should sound human, that control goes a long way. Supported tags differ by language in the multilingual release.
Low Latency Streaming
Streaming latency lands around 200 milliseconds, and the docs note it can drop toward 100 milliseconds with input streaming. For realtime use like voice assistants, that gap decides whether a conversation feels natural. The package streams audio chunks as they generate, so you can start playback before the full clip is ready.
Multiple Model Sizes
Beyond the English finetuned and pretrained models, the project plans a range of smaller versions at 1B, 400M, and 150M parameters. Smaller models trade some quality for speed and lighter hardware, which matters when you deploy on modest machines. The roadmap lists these as upcoming releases.
Fine-Tuning on Your Own Voice
The repo ships training and data processing scripts so you can adapt the base model to your own speaker. Results start to look good after about 50 examples, and the team suggests aiming for 300 per speaker for the best output. The process mirrors tuning a language model with Trainer and Transformers, so an ML background helps.
Multiple Ways to Run It
You can run Orpheus TTS through the Python package, a no-GPU path with llama.cpp, or a dedicated deployment through Baseten, the project's preferred inference partner. Community builds add an OpenAI-compatible API and a Gradio web interface. Pick the path that fits how you plan to ship.
Pros and cons
Pros
- Speaks with natural emotion and rhythm that competes with closed source models
- Clones a voice zero-shot from a short sample, no fine-tuning required
- Streams audio at roughly 200ms latency for realtime apps
- Open source weights and code, so you can run it yourself
- Emotion tags give fine control over delivery
Cons
- No official hosted API, so you host and maintain it yourself
- Needs a GPU for fast inference, and the base model file is large
- Output quality depends on the reference clip, so noisy audio drags results down
- The full multilingual family is still a research preview
Frequently asked questions
Orpheus TTS turns text into natural sounding speech and can imitate a chosen voice. Developers use it for voice assistants, narration, dubbing, and research into speech models. It's a building block you plug into a larger project rather than a standalone product.
Related content
Explore related tools, skills, and articles for Orpheus TTS.
Orpheus TTS Alternatives

Prosp
Prosp · Writing · Voice & Language · MarketingProsp is an AI LinkedIn outreach tool built for agencies and sales teams, and it writes the message and the voice note in your own voice for each prospect so they actually reply. You connect your accounts, find leads, and let the AI draft and send personalized messages at scale, all from one inbox. It's built for people running outbound at volume. That's the whole pitch. Every touchpoint still has to feel human.

Wordly AI Translation
Wordly · Voice & Language · ProductivityWordly AI Translation is a real-time AI translation and captioning platform built for meetings, conferences, and events. It delivers live translation, captions, transcripts, and summaries in more than 60 languages, and attendees join by scanning a QR code or opening a link instead of using dedicated headsets. The platform works with Zoom, Microsoft Teams, Google Meet, and Webex, and it's designed for organizations that want multilingual access without hiring human interpreters for every session. Simple as that.
Musicful
Musicful AI · Voice & Language · VideoMusicful is an AI music generator and AI music video maker that turns text to music in minutes. Give it a text prompt, a set of lyrics, or a hummed melody and it returns a finished track with vocals and instruments. It also doubles as an AI song generator, produces music videos from the songs you create, and offers an AI cover tool plus a developer API. The platform runs in a web browser and through an Android app, so you can start a song on desktop and pick it up on your phone.