
QwQ-32B
Alibaba (Qwen team) · Business · Other
QwQ-32B is Alibaba's open-weight reasoning model from the Qwen team, built to solve math and coding problems through step-by-step thinking while running on a single own GPU.
About QwQ-32B
What Is QwQ-32B
QwQ-32B is a reasoning language model from Alibaba's Qwen team, released in March 2025 under the Apache 2.0 license. It carries 32 billion parameters and descends from Qwen2.5-32B, the general model the team started from. Instead of answering right away, it writes out a long chain of thought, checks its own steps, and only then commits to a final answer. That habit is what people call reasoning, and it's why the model does well on questions that punish guesswork.
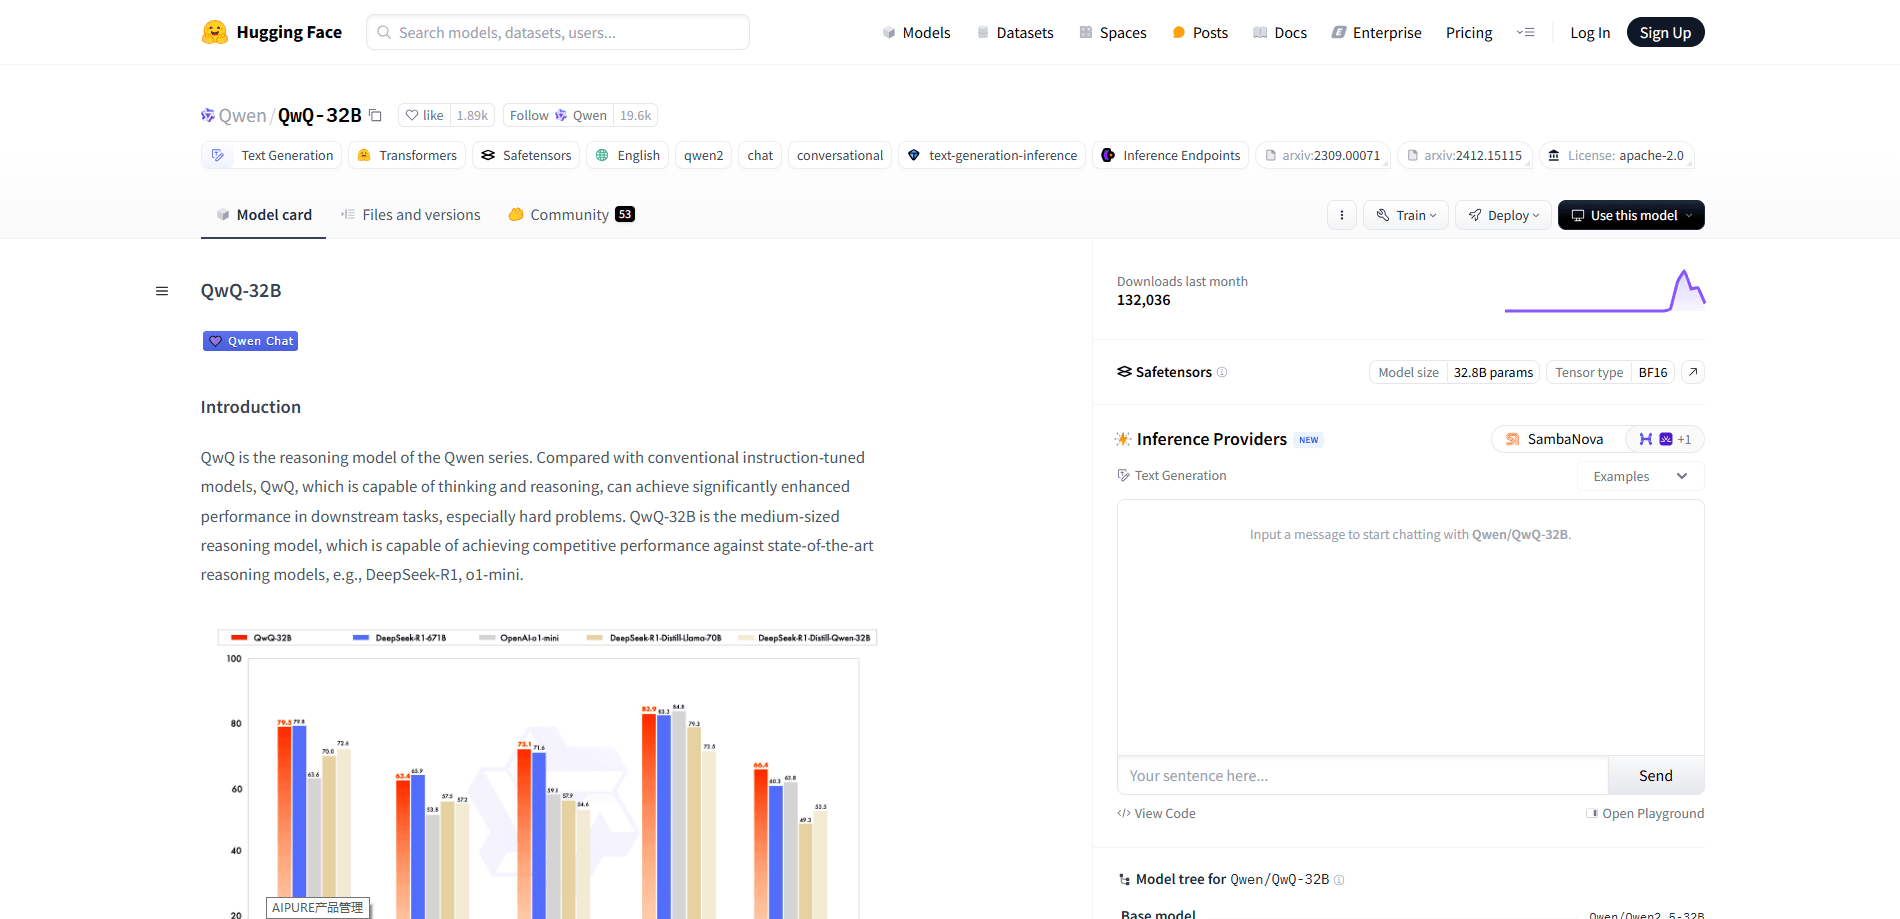
As an open source reasoning model, it's also one you can inspect rather than rent. The headline claim, per the Qwen team, is that QwQ-32B performs on par with DeepSeek-R1, a model with 671 billion parameters. The team credits reinforcement learning, not size, for closing that gap: they scaled RL on math and coding tasks, then added a second round for general skills. For you, the practical takeaway is a strong reasoner small enough to run yourself.
The main limit is scope. QwQ-32B thinks before it speaks, so it's slow on anything trivial, and its weights are frozen at the original release. Newer Qwen models now cover more languages and switch between fast and deep modes, so QwQ-32B is best seen as a focused reasoning tool rather than a do-everything assistant.
Getting Started
- Download the weights from Hugging Face or ModelScope, or pull the quantized build with
ollama run qwq - Load the model through an inference server such as vLLM, SGLang, or Ollama, depending on your hardware
- Send a prompt through the OpenAI-compatible endpoint the server exposes, and read the reasoning trace before the final answer
- For hosted access, call the Qwen API on Alibaba Cloud's Model Studio with the model name
qwq-32b
Product Information
A quick look at QwQ-32B's pricing, supported platforms, and performance.
Best for
The users, tasks, and scenarios where this tool fits best.
Users
- Developers who want a reasoning model on their own hardware
- Students and self-learners working through math or code problems
- Researchers comparing reasoning models
Tasks
- Solving competition-style math problems
- Writing and debugging code
- Building tool-using agents
- Quantized local inference
Scenarios
- Keeping private data in house
- Offline or air-gapped work
- Prototyping a reasoning feature
Key features
Long chain-of-thought reasoning
QwQ-32B works through a problem in explicit steps before it gives an answer. You can read that reasoning, spot where it went wrong, and rephrase the prompt. It's the difference between a model that sounds confident and one you can actually check.
Math and coding performance near much larger models
The Qwen team reports that the QwQ-32B benchmark scores match DeepSeek-R1 on tests like AIME and LiveCodeBench, despite the size gap. Those are the two areas built into its training, so it's the natural fit when numbers or code are involved.
Tool calling inside the reasoning loop
QwQ-32B can call functions mid-thought and fold the results back into its plan. If a task needs live data or an external action, the model decides when to reach for a tool instead of guessing. That makes it usable as the brain of an agent, not just a chat partner.
Open weights under Apache 2.0
The full weights are downloadable and permissively licensed, so you can fine-tune, quantize, or ship them inside a product. Nothing is locked behind a vendor account, which matters when you build on top of a model.
Runs on a single GPU when quantized
At full precision the model needs a lot of memory, but 4-bit builds cut it down to fit a consumer card. You get reasoning that used to require a data center, on one machine you own.
OpenAI-compatible serving
Servers like vLLM and SGLang expose QwQ-32B through an OpenAI-style API. You point your existing code at a new URL and key, and it runs, so switching over takes minutes rather than a rewrite.
Pros and cons
Pros
- Reasoning quality that competes with models many times its size, per the Qwen team's benchmarks
- Open weights under Apache 2.0, so you can self-host, fine-tune, and ship it freely
- Quantized builds run on a single consumer GPU, which keeps private data local
- Tool calling works inside the reasoning loop, making it a solid base for agents
- An OpenAI-compatible server means little code changes to adopt it
Cons
- It's slow by design: every trivial question triggers a full thinking pass, so chat-style use feels sluggish
- The weights are frozen at the 2025 release, so you miss the newer language and mode features that landed in later Qwen models
- Full-precision memory needs are high, so you can't skip quantization on modest hardware
- Training leaned toward math and code, so open-ended writing or niche languages may lag behind a general-purpose model
Frequently asked questions
It's an open-weight reasoning language model from Alibaba's Qwen team. It has 32 billion parameters and works through problems step by step before answering, which is what makes it strong on math and coding.
Related content
Explore related tools, skills, and articles for QwQ-32B.
QwQ-32B Alternatives

Knocket
Knocket (Tencent RTC team) · Productivity · Business · ChatbotKnocket is a free live chat and contact page tool that lets visitors message you from your website, app, or a shareable link, with every reply handled from Telegram or one inbox.

shippedit.me
Krawlup · Marketing · Businessshippedit.me now redirects to Krawlup, a web platform that audits SEO, AEO and page speed every week, then hands the fixes to AI coding agents over MCP.

Ayven
Alknoma · Productivity · BusinessAyven is an AI control centre by Alknoma that turns a plain-language goal into a dated plan, hands the work to your people and AI agents, and asks for your approval only when the call is yours.