
Reflection 70B
HyperWrite · Writing · Chatbot
Reflection 70B is an open-weight model from HyperWrite. Built on Llama 3.1 70B, this self-correcting LLM checks its own reasoning before answering.
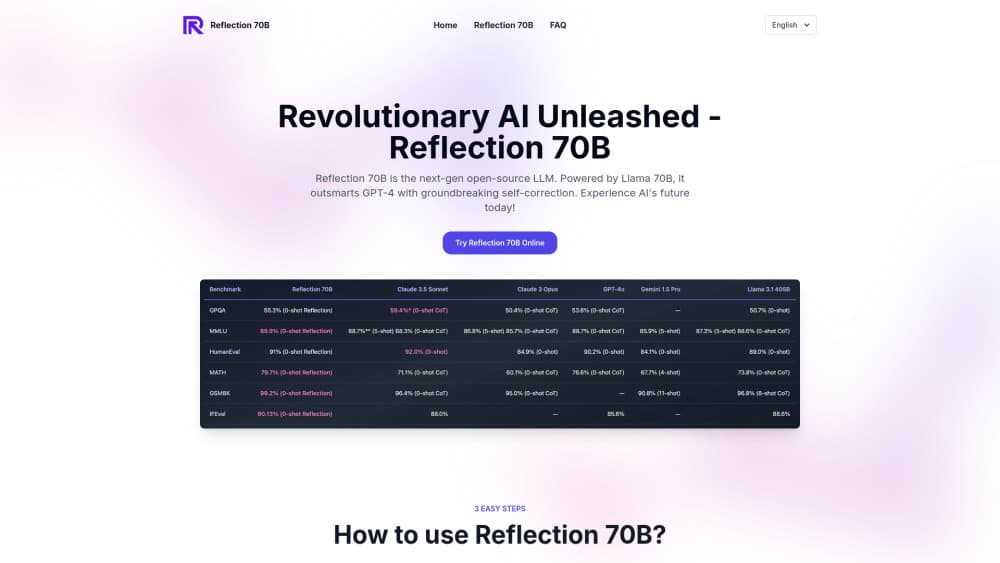
About Reflection 70B
What Is Reflection 70B
Reflection 70B is a reasoning-focused language model from HyperWrite, released in early September 2024 and built on top of Meta's Llama 3.1 70B Instruct. Its selling point is a training method called Reflection-Tuning, which teaches the model to spot mistakes in its own chain of thought and fix them before it commits to a final answer. The model writes its thinking inside <thinking> tags and its final answer inside <output> tags, adding a <reflection> block whenever it catches an error mid-reasoning.
The idea tackles a real frustration. Standard LLMs hallucinate. They rarely notice when they do. Reflection 70B was trained to notice. According to HyperWrite, the model beat GPT-4o and even Llama 3.1 405B across benchmarks like MMLU, MATH, IFEval, and GSM8K. Those numbers pulled in enormous attention at launch.
That early hype didn't survive contact with third parties. Independent evaluators, including Artificial Analysis, couldn't reproduce the headline scores. Later testing found versions released on Hugging Face performing worse than the plain Llama 3.1 70B it was built on. Some users also accused the hosted API of quietly routing requests to Claude. HyperWrite's Matt Shumer acknowledged the model fell short of its reported benchmarks.
So the honest takeaway is a split one. The Reflection-Tuning approach is genuinely interesting. The model as shipped never matched its own marketing. Open-weight model releases like this one are still worth studying, even when the launch pitch oversells them.
Getting Started
- Open the model page on Hugging Face (mattshumer/Reflection-70B) or a mirror, and accept the license terms.
- Download the weights, or skip local setup and run it through a hosted inference provider.
- Load it with the same code you'd use for any Llama model, since it shares Llama's chat template.
- Prompt it with the reasoning system message so it outputs thinking, reflection, and answer sections in order.
- Read the
<reflection>tags if you want to see where the model changed its mind.
Product Information
A quick look at Reflection 70B's pricing, supported platforms, and performance.
Best for
The users, tasks, and scenarios where this tool fits best.
Users
- AI researchers
- Developers building local reasoning tools
- Hobbyists curious about reflection prompts
Tasks
- Math and logic problems
- Prototyping self-check pipelines
- Comparison studies
Scenarios
- Running a reasoning model without sending data to a closed API
- Studying evaluation pitfalls
- Experimenting with reflection prompts on a budget
Key features
Reflection-Tuning
Reflection-Tuning is the technique that gives the model its name. Instead of only training on final answers, it trains the model to review its own reasoning and revise it mid-generation. In practice the model produces a draft of its thinking, checks it, and rewrites the parts it judges wrong before delivering an answer. That ordering is the whole idea: correct, then commit.
Structured Thinking and Output Tags
The model separates its internal work from its answer using special tokens. Reasoning goes inside <thinking> tags, and the final response goes inside <output> tags. This split keeps the scratch work visible, which is handy when you want to debug why a model reached a conclusion, or when you'd rather hide the thinking and show only the answer.
Inline Self-Correction
When the model notices a mistake, it emits a <reflection> block inside its thinking. You can read that block to see exactly where the reasoning turned. For tasks with a single right answer, that visible pivot is often more useful than the answer itself, because it shows the model catching its own slip rather than burying it.
Llama Compatibility
Because it builds on Llama 3.1 70B Instruct and keeps the standard Llama chat format, Reflection 70B drops into tools and pipelines that already support Llama. If you've deployed a Llama model before, the loading code and serving setup carry over with little change. That compatibility is why the model was easy for people to test in the first place.
High-Precision Reasoning Focus
The model targets tasks that reward accuracy over speed, like multi-step math and logic. It breaks reasoning into distinct steps and spends more tokens double-checking them. The tradeoff is latency. Answers take longer to arrive, and token costs climb, because reflection means writing more text before you get the final line.
Open Weights
The weights are publicly available, so you can run the model on your own hardware, fine-tune it, or study how reflection training changed its behavior. Open weights also mean you aren't locked into a single vendor's pricing or rate limits, which matters if you're testing the model at any scale.
Pros and cons
Pros
- Open weights you can download, inspect, and self-host
- Built on Llama 3.1 70B, so it works with existing Llama tooling and serving stacks
- Visible self-correction through thinking, reflection, and output tags
- Free to run locally, with cheap hosted inference when you'd rather not manage GPUs
Cons
- Independent benchmarks never confirmed the launch performance claims
- Some Hugging Face releases reportedly scored below plain Llama 3.1 70B
- Long thinking and reflection steps add latency and token cost
- The hosted API drew accusations of routing traffic to Claude, which hurt trust
Frequently asked questions
It's an open-source language model from HyperWrite, built on Llama 3.1 70B Instruct, that uses a training method called Reflection-Tuning to check and correct its own reasoning before answering.
Related content
Explore related tools, skills, and articles for Reflection 70B.
Reflection 70B Alternatives

Google EmbeddingGemma 2
Google DeepMind · Writing · Image · CodingGoogle EmbeddingGemma 2 is a 740M-parameter open model that turns text, code, images, audio, and video frames into vectors in one 768-dimension space, running on phones and laptops.

MePersona
MePersona, Inc. · Writing · Productivity · MarketingMePersona is an AI unified inbox for creators. It learns your voice, drafts replies to fan messages from 12 platforms, and sends only what you approve.

Fluence
Yay Software (Yannick Huchard) · Writing · Voice & Language · ProductivityFluence is an Android app that reads PDFs, EPUBs, Word files and web articles aloud, follows each sentence as it speaks, and answers questions about the text on the phone itself.