
Ollama
Ollama · Image · Other
Ollama is a local AI runtime to run large language models on your own machine. It downloads open models like Gemma 4, Qwen, and gpt-oss, with a cloud option for bigger ones.
About Ollama
What Is Ollama
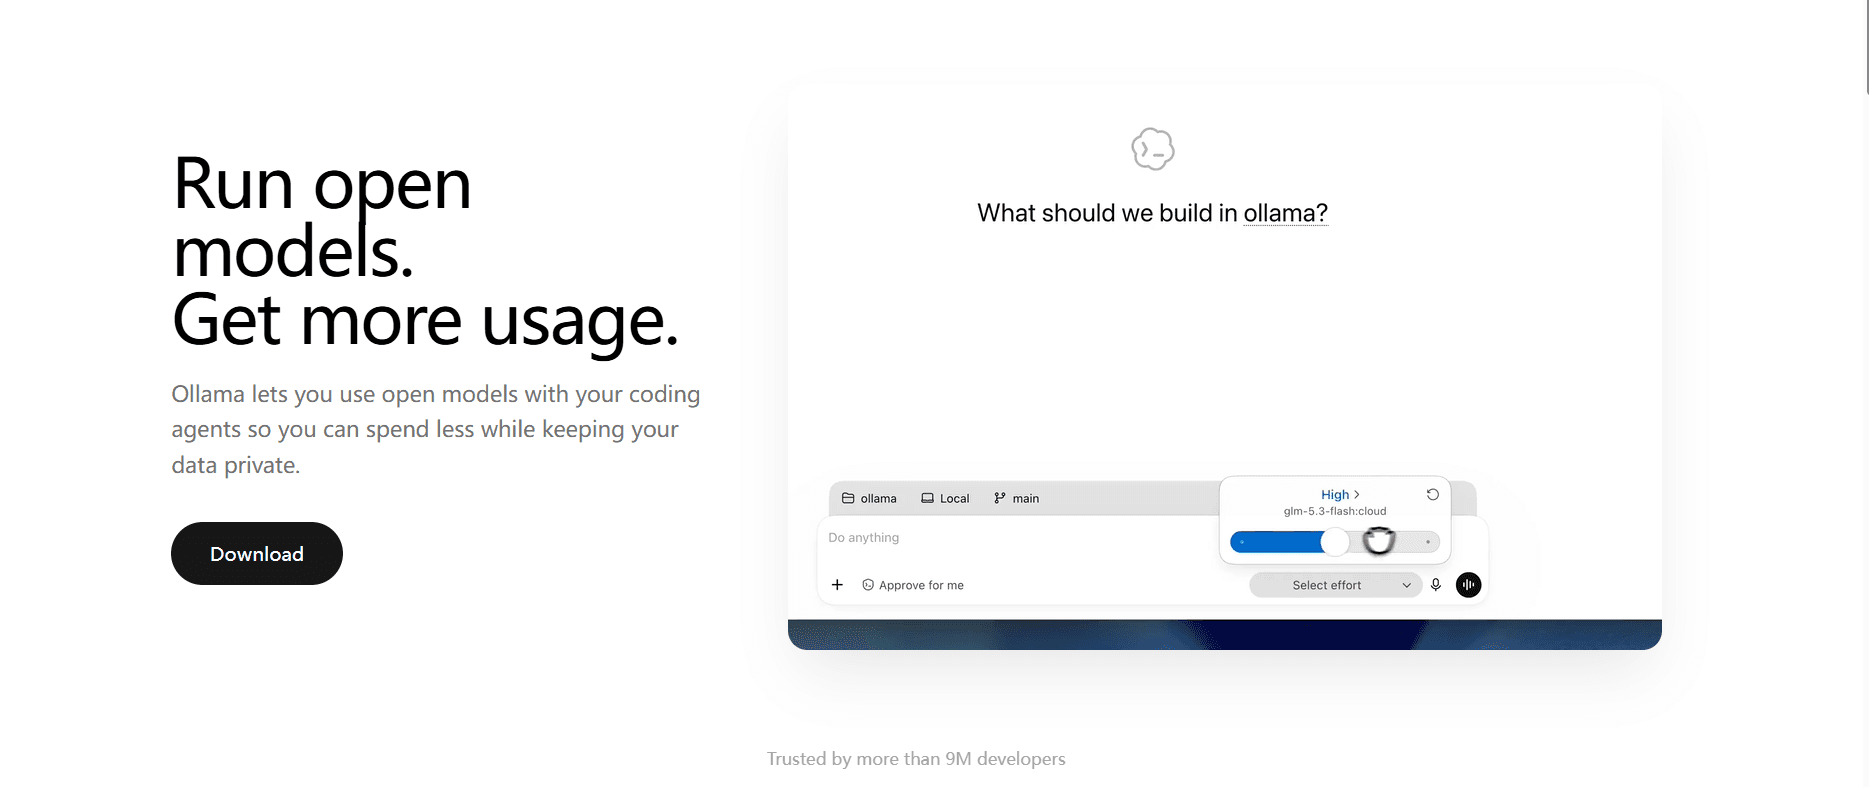
Ollama is an open-source runtime that runs large language models on your own computer. Instead of renting a model through an API, you pull weights once and chat with them offline. One command downloads and launches a model, and the app handles the messy parts: quantization formats, GPU or Apple Silicon offload, memory limits, and the server process that answers requests.
The project started in July 2023 and grew fast, reaching north of 9 million installs a month and more than 1 billion model downloads. In 2026 the company raised $88 million from Benchmark, Y Combinator, and others, and added a cloud tier for models too big to fit on a laptop.
That cloud tier is the main tradeoff to understand. Running models locally is always free and unlimited, but it is capped by your hardware; a 7B model runs on a modest laptop, while a 200B model needs a real GPU box. Cloud models remove that ceiling and bill by token, so Ollama is now both a free local tool and a pay-as-you-go service, depending on which model you pick.
Getting Started
- Download Ollama for macOS, Windows, or Linux, or run the official Docker image, and open the app.
- Pull a model with
ollama pull gemma4:e2b(the download is about 7.2 GB), or choose Local during setup if you do not want an account. - Run
ollama run gemma4:e2bto start an interactive chat in your terminal, or launch a coding agent withollama launch claude. - For apps, send a request to the local REST API at port 11434, or point an OpenAI or Anthropic client at Ollama's compatible endpoints.
- Sign in and add an API key when you want cloud models, then keep large prompts off your own hardware.
Product Information
A quick look at Ollama's pricing, supported platforms, and performance.
Best for
The users, tasks, and scenarios where this tool fits best.
Users
- Developers who want to test open models without cloud bills
- Privacy-focused users handling sensitive text
- Teams deploying coding agents
- Researchers comparing model families
Tasks
- Running a chat model offline
- Building AI features into an app
- Fine-tuning chat behavior with a Modelfile
- Connecting agents and editors
- Getting structured data from a model
Scenarios
- A laptop on a plane
- A company with strict data rules
- A quick prototype before committing to a cloud bill
- A coding session with a local agent
Key features
One-Command Local Models
The core promise is a single line: ollama pull fetches the weights and ollama run starts a chat. Ollama handles quantization, memory offload, and the model server behind the scenes, so you skip the usual dance of CUDA versions and Python environments. Models come from a built-in library that covers Gemma, Qwen, gpt-oss, DeepSeek, Kimi, MiniMax, GLM, Mistral, and Nemotron.
Cloud Models With Per-Token Pricing
Not every model fits on a laptop, so Ollama added a cloud tier that runs larger open models on NVIDIA Cloud Provider hardware. You pay per million tokens, with off-peak rates that cut the price roughly in half outside weekday business hours. Free accounts get starter credits; paid plans bundle a monthly credit allowance.
REST API and OpenAI Compatibility
Every local model exposes an HTTP server on port 11434, so any language can talk to it. Ollama also speaks the OpenAI Chat Completions and Responses formats and the Anthropic Messages format, which means tools built for those APIs work with a one-line base URL change, usually with no code edits.
MLX Engine on Apple Silicon
On Macs, Ollama runs supported models through Apple's MLX framework instead of a translated runtime. The shift brought large speed gains in 2026, including multi-token prediction that the company measured as up to 90% faster on coding agents. Memory use also dropped, which matters on unified-memory Macs where RAM is the hard limit.
Coding Agent and Desktop Integrations
ollama launch claude, ollama launch codex, and similar commands connect coding agents to your models. On the desktop side, Claude and ChatGPT (Desktop) can be pointed at Ollama, opening up models like Muse Glimmer and Nemotron inside tools people already use.
Modelfiles and Model Creation
A Modelfile is a short recipe that defines a custom model: base weights, system prompt, parameters, and a template. You build it with ollama create, and the definition travels with the model, so shared instructions stay consistent across a team instead of living in scattered notes.
Embeddings and Structured Outputs
Ollama runs embedding models such as EmbeddingGemma and returns vectors for search or clustering. The format parameter accepts a JSON schema so a model answers with a typed object, which turns free text into data a program can read without guessing at the shape.
Decision Models
Newer releases add decision models that return choices, scores, and probabilities instead of prose. Based on TypeSafe's Jev API, they handle jobs like ticket triage and content classification, and Ollama runs them through a dedicated endpoint alongside the usual chat models.
Pros and cons
Pros
- Local models are free and unlimited, with no account, API key, or internet connection needed.
- Installation is a single command, and the built-in model library skips the usual environment setup.
- The REST API and OpenAI and Anthropic compatible endpoints let existing clients switch over with one URL change.
- Apple Silicon support through MLX brings big speed gains for Mac users.
- Cloud models let you run large open models without owning a GPU.
Cons
- Local performance is bound by your hardware, so big models need real VRAM and a laptop will struggle with them.
- Cloud pricing depends on the model and time of day, which makes a monthly bill harder to predict.
- Some advanced cloud features, like running several models at once, are limited on the free plan by concurrency caps.
- The model library, while broad, is smaller than the full range available on Hugging Face or through the big cloud providers.
Frequently asked questions
Ollama is a runtime for running open large language models on your own computer or in the cloud. It downloads the models, starts a local server, and gives you a command line, a desktop app, and an API to work with them.
Related content
Explore related tools, skills, and articles for Ollama.
Ollama Alternatives

Google EmbeddingGemma 2
Google DeepMind · Writing · Image · CodingGoogle EmbeddingGemma 2 is a 740M-parameter open model that turns text, code, images, audio, and video frames into vectors in one 768-dimension space, running on phones and laptops.

Tractionwave
TractionWave · Image · MarketingTractionWave is an AI attention heatmap tool for static ads. Upload a PNG or JPG and it returns predicted attention, ranked hotspots, and fixes before you spend budget.

Imejis.io
Imejis.io · Image · MarketingImejis.io is an AI design studio for agents and marketing teams. Describe an image in plain words, and it writes the copy, builds the layout, reflows it to every size, then exports a finished file.