
OCR Arena
Extend · Image · Business
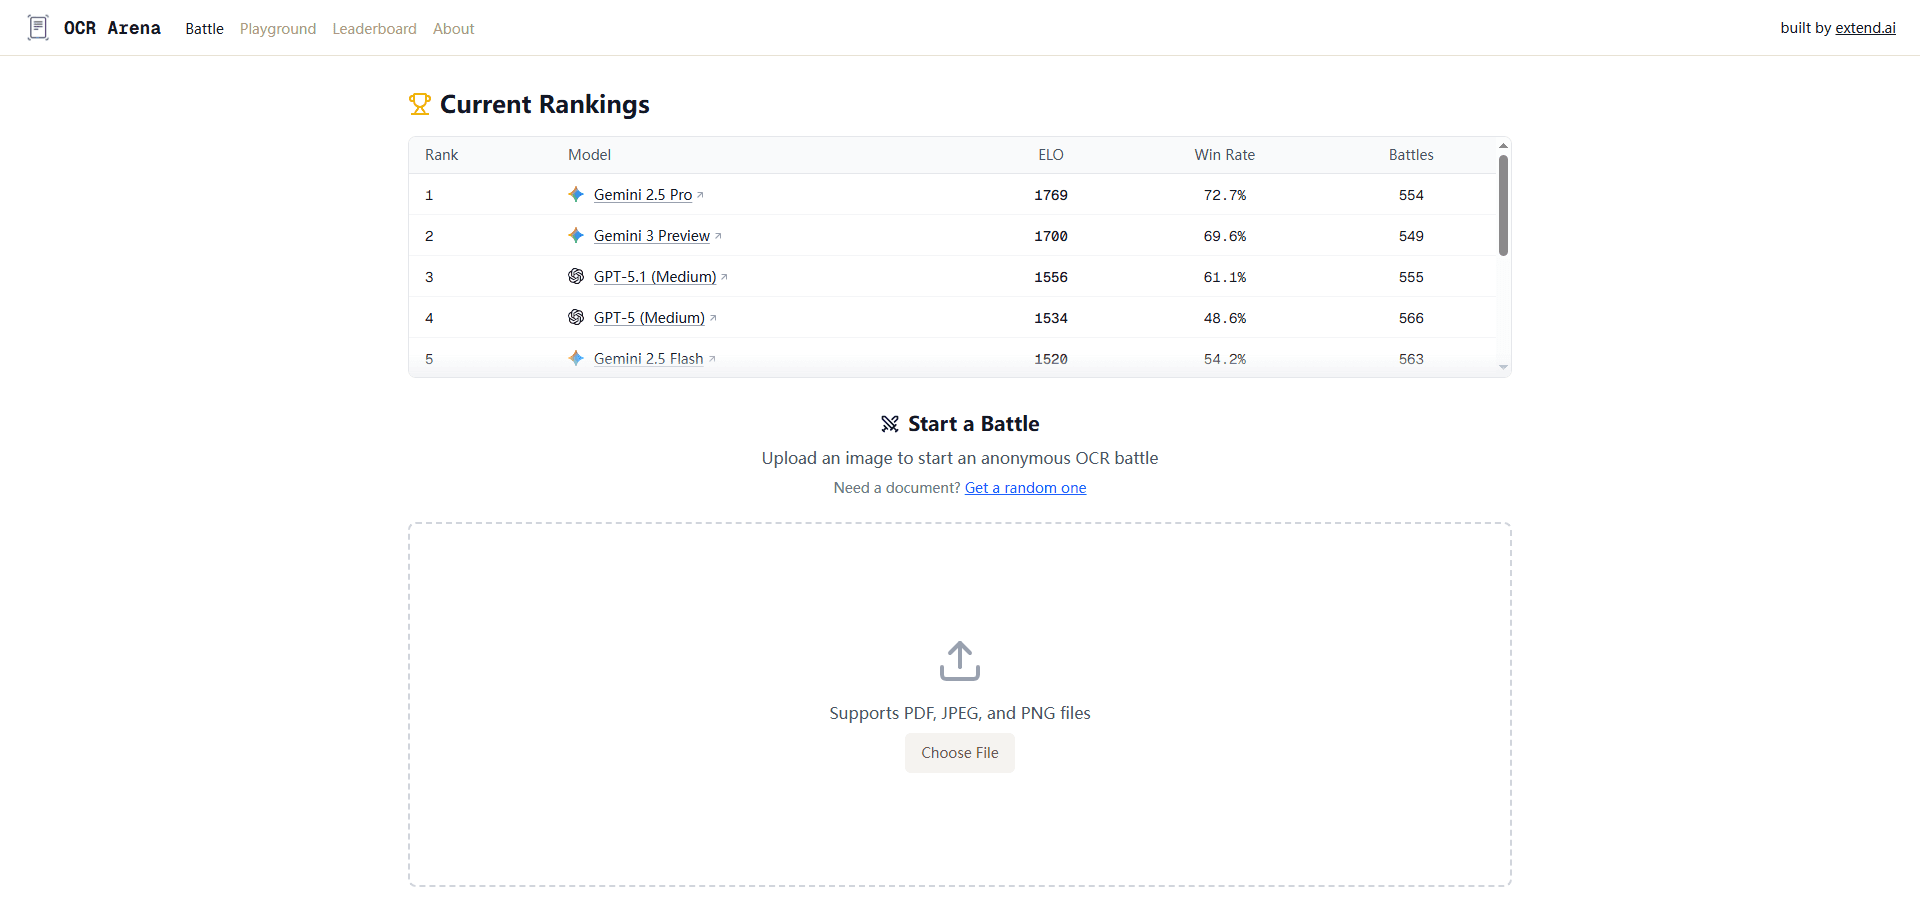
OCR Arena is a free, no-login platform for OCR model comparison on real documents. You upload a PDF, JPEG, or PNG, two anonymous models parse it side by side, and you pick the better output. Every vote feeds a public OCR leaderboard, so the rankings reflect what people actually see on their own files rather than vendor benchmarks. The tool was built by the team at Extend and launched with more than 10 models.
About OCR Arena
What Is OCR Arena
OCR Arena is a browser-based arena for document parsing models. It covers foundation vision-language models and dedicated open source OCR engines, letting you judge them on your own files instead of a fixed test set. There's no account and no cost.
The problem it solves is simple. New OCR models ship every few weeks, and picking one is guesswork. Published benchmarks rarely match how a model behaves on a messy receipt, a scanned form, or a two-column PDF that someone photographed at an angle under bad office lighting. Here you get blind model battles built from documents people actually uploaded.
The catch is that it's a comparison tool, not an OCR service. You can't plug OCR Arena into your app to extract text at scale. There's no API for processing your backlog of files, and it doesn't give you structured JSON output you could feed into a pipeline. Think of it as an OCR evaluation tool, a testing ground to decide which engine you then go use elsewhere. Not a production pipeline.
Getting Started
- Open ocrarena.ai in a browser. No sign-up, email, or login is required.
- Upload a document. PDF, JPEG, and PNG are supported, and you can pull a sample if you don't have one handy.
- Watch two unnamed models parse the same file side by side.
- Vote for the output you find more accurate. Your pick moves both models in the ELO rankings.
- Check the leaderboard to see where the models sit after thousands of battles.
Product Information
A quick look at OCR Arena's pricing, supported platforms, and performance.
Best for
The users, tasks, and scenarios where this tool fits best.
Users
- Developers picking an OCR model
- Document-heavy teams
- AI researchers and tinkerers
Tasks
- Document parsing evaluation
- Text extraction accuracy testing
- Model shortlisting
Scenarios
- Deciding between a general vision-language model and a specialized OCR engine for a new intake pipeline.
- Sanity-checking a vendor's accuracy claim against your own document set.
- Staying current as new models land, since the leaderboard grows as releases arrive.
Key features
Blind Head-to-Head Battles
The core of OCR Arena is the anonymous matchup. You upload one document, and two models parse it without labels, so you can't favor a brand you recognize. You vote on which output is closer to the original, and the system records the result. It's the same blind model battles format that made chatbot arenas popular, aimed at document parsing instead of chat.
Public ELO Leaderboard
Every vote updates a shared leaderboard built on the ELO rating system. Models all start at 1500, and the winner of each battle gains points while the loser drops, using a fixed volatility factor of 20. The result is a ranking that shows win rates and total battle counts together, so you can see both a model's position and how much evidence actually backs it up.
Broad Model Coverage
The arena launched with more than 10 models and adds new ones as they're released, which means the mix you compare spans foundation vision-language models and dedicated OCR engines that were built for very different purposes. Neither type wins outright. That mix gives you a fairer picture of the field than any single-vendor test could.
No-Login Document Upload
You can start testing in seconds, because there's no account wall and no paywall standing between you and a first result. Just upload a PDF, JPEG, or PNG, or grab a sample file the site provides, and the battle begins.
Document Parsing Focus
The arena is tuned for document parsing, not just text recognition. That means tables, multi-column layouts, and formatted sections are the kinds of files worth testing. That matters. A clean receipt is easy for almost any model. If your hardest cases involve structure rather than clean type, this is where the tool earns its keep. Wondering whether a general model beats a dedicated engine on your files? That's exactly the question a battle answers, and you get the result in under a minute without writing a single line of code.
Pros and cons
Pros
- Completely free with no sign-up, so there's zero commitment to start comparing models.
- Blind battles strip out brand bias and show you output quality directly.
- A shared ELO leaderboard turns scattered votes into a ranking you can scan in a minute.
- Roster grows with new model releases, so it stays current without you hunting for test setups.
- Works on the document types that matter most: scanned PDFs, photos, and multi-column layouts that would break a naive text extractor.
- Every battle counts toward a shared ranking, so even a quick one-off test you run today adds evidence that helps everyone else pick a model later.
Cons
- It's an evaluation playground only. There's no API or bulk processing, so you can't use it to extract text at scale.
- You get a winner per battle, not detailed error reports or per-field accuracy breakdowns, which makes fine-grained tuning harder.
Frequently asked questions
It's used to test and compare OCR models on real documents. You upload a file, watch two models parse it, and vote on the better result, which feeds a public leaderboard. It's for choosing a model, not for running OCR at scale.
Related content
Explore related tools, skills, and articles for OCR Arena.
OCR Arena Alternatives

X Ray Interpreter
X-ray Interpreter · ImageX Ray Interpreter is a web-based AI radiology tool that turns X-rays, CT scans, MRI, ultrasound, and PET images into plain-language reports. You upload a scan, get a preliminary X-ray interpretation in moments, then ask follow-up questions if something needs explaining. It works as a second opinion and a learning aid, not as a medical diagnosis.

Aieasypic
AIEasyPic · ImageAIEasyPic is an AI image generator that turns plain text prompts into finished artwork in seconds. You can also train custom models on your own photos, swap faces in existing images, and create short video clips from text, all from a browser. It suits casual creators who want quick visuals and hobbyists who want to build a personal model without touching any code.
Chargen
Chargen · ImageChargen is an AI character generator and worldbuilding toolkit built for Dungeons & Dragons and other tabletop RPGs. It turns a one-line idea into a painted character portrait, spins up NPCs, monsters, maps and encounters from the same session, and keeps every creature's details close at hand. The tabletop RPG art side runs on a credit system called Gold, while the text generators stay free for everyone.