
Polarity
Polarity · Coding
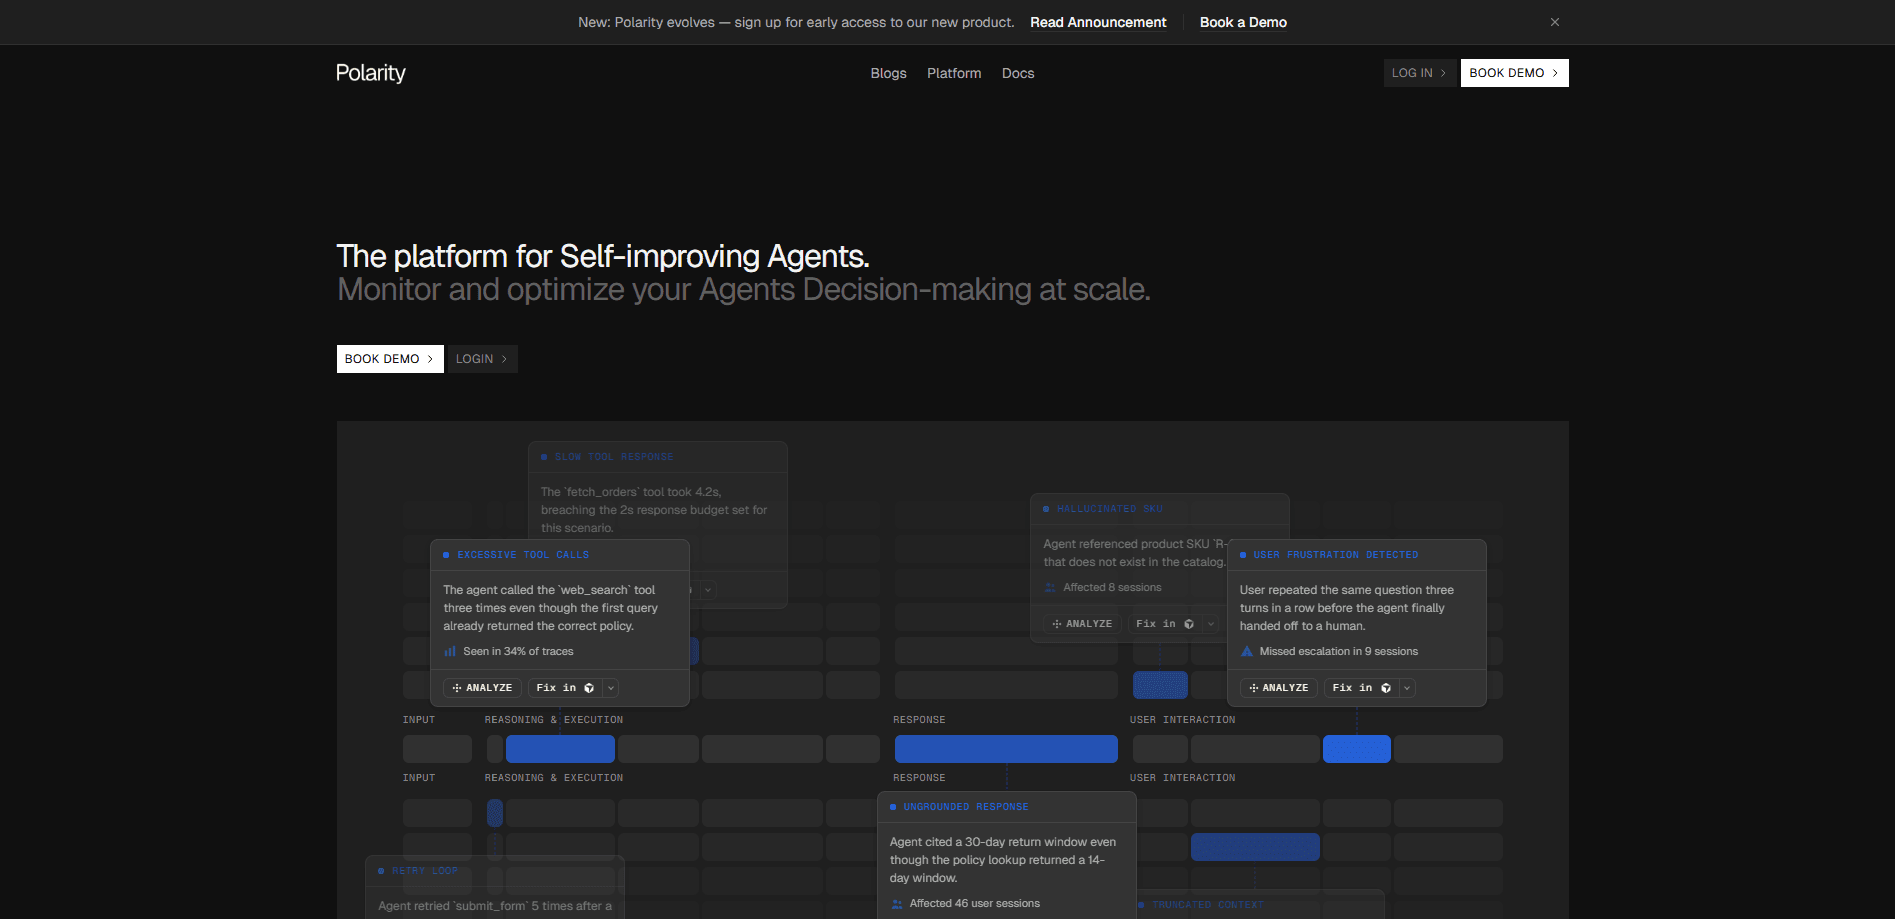
Polarity is a sandboxed evaluation and monitoring platform for AI agents. It runs your agent inside isolated Docker environments with real backing services, scores what the agent does against invariants and forbidden rules, and measures how much its behavior varies across repeated runs. That last part is the one most teams skip. Think of it as an agent eval tool that treats live behavior as the test. When a run fails, seed-based replay lets you rebuild the exact conditions and debug the failure instead of guessing.
About Polarity
What Is Polarity
Polarity is an evaluation platform built for teams shipping AI agents. Instead of testing agents against a scripted mock, it runs them in a sandboxed Docker environment wired to real backing services, so the agent sees the same APIs, databases, and tools it would touch in production. That setup matters, because most agent failures don't come from a bad answer. They come from the agent taking an action nobody wanted it to take.
The platform checks two things at once. First, whether each run respects the rules you set, which Polarity splits into invariants that must always hold and forbidden rules that must never fire. Second, how stable the behavior is. Running the same task across several replicas surfaces non-determinism that a single pass would hide entirely. Variance is the tell. And that distinction matters, because an agent that passes one run and fails the next is the kind that quietly breaks production long after everyone stopped watching it.
The main limit is scope. Polarity is a developer tool, not a consumer app, so you'll need your agent packaged and your backing services reachable from the sandbox before you get value. Teams with no automated test setup yet will spend their first few days wiring things up.
Getting Started
- Sign in at the Polarity website and create a project for the agent you want to evaluate.
- Point the project at your agent and define the backing services it needs, so the sandbox comes up with the same dependencies production has.
- Write your invariants and forbidden rules as the checks each run gets scored against.
- Run a task in one or more replicas to see whether behavior holds steady or drifts between attempts.
- Open any failure, replay it from its seed, and fix the root cause before shipping.
Product Information
A quick look at Polarity's pricing, supported platforms, and performance.
Best for
The users, tasks, and scenarios where this tool fits best.
Users
- AI engineering teams
- Platform and infrastructure engineers
- QA and reliability leads
Tasks
- Scoring agent behavior
- Catching non-determinism
- Debugging failures
- Agent regression testing before release
Scenarios
- Shipping a new agent to production
- Debugging an intermittent agent failure
- Auditing an agent after a model swap
Key features
Sandboxed Runs With Real Services
Polarity executes each agent task inside a Docker sandbox for AI agents rather than a mocked test rig. The sandbox is wired to real backing services, so the agent interacts with genuine APIs and data stores during evaluation. That means the behavior you score is closer to what users will actually experience.
Invariant and Forbidden Rule Scoring
Each run is graded against two rule types. Invariants describe conditions that must hold in every run, while forbidden rules names the actions that must never happen. Writing these down forces a team to agree on what "correct" means, which is often the harder part.
Non-Determinism Measurement
Agents don't behave identically every time, and a single passing run proves very little. Polarity runs the same task across multiple replicas and compares the outcomes, so you can see how much the agent drifts between attempts. High variance is usually the first sign of a fragile prompt or an unstable tool.
Seed-Based Replay
When a run fails, Polarity can replay it from its original seed. Replay rebuilds the same conditions that produced the failure, which turns an intermittent bug into something you can inspect, fix, and verify. For teams used to chasing flaky agents by hand, this is the feature that saves the most time, because reproducing a failure that only shows up one time in twenty used to mean running the whole thing over and over until it happened to break again.
Monitoring for Deployed Agents
Evaluation doesn't stop at the code review. Polarity also handles AI agent monitoring once agents are running, scoring live behavior against the same rules you used in testing. You catch a rule violation in production rather than hearing about it from a user.
Pros and cons
Pros
- Real services in the sandbox mean scores reflect production behavior, not a simplified mock.
- Invariant and forbidden rule scoring gives a clear, testable definition of correct behavior.
- Replica runs make non-determinism visible, which most single-pass eval tools miss.
- Seed-based replay shortens the debug loop for intermittent failures.
- Monitoring extends the same rule set from testing into production.
Cons
- No free tier, and pricing isn't published, so you have to talk to sales before you can judge cost.
- It's a developer tool, so getting value depends on your agent and services already being packaged to run in a sandbox.
- Storing and running real backing services raises setup effort and infrastructure cost compared with mock-based eval tools.
- Not ideal for teams that just want a quick demo. Polarity assumes you're already testing.
Frequently asked questions
It evaluates and monitors AI agents. You define rules, Polarity runs your agent in a sandboxed Docker environment with real services, scores each run against those rules, and lets you replay failures. So what does that buy you? Fewer surprises when the agent goes live.
Related content
Explore related tools, skills, and articles for Polarity.
Polarity Alternatives
Forefront
Forefront · CodingForefront is a web platform for building with open-source AI. It lets you fine-tune leading open-source language models on your own data, evaluate how they perform, and run them through an API or export them to host yourself. Developers who want the convenience of a closed-source platform but insist on owning their models and data are the target audience here.

Startkit
StartKit.AI · CodingStartkit is a boilerplate for building AI SaaS and AI wrapper products. Think of it as an AI startup boilerplate with the boring parts already wired up: authentication, Stripe and Lemon Squeezy payments, usage limits, transactional email, and an AI API starter that talks to OpenAI, Anthropic, Groq, or Llama. You clone the repo, set your price, and start on the part of your product that people actually pay for. It's Next.js under React and Tailwind, so most of the boilerplate code already feels familiar.
Testim
Tricentis · CodingTestim is an AI-powered test automation platform for building and running end-to-end tests across web, mobile, and Salesforce applications. It leans on machine learning to keep tests stable when an interface changes, so teams spend less time fixing broken selectors. Not bad for an automated testing tool you can start using today. You create tests by recording actions in a browser, then optionally add JavaScript when you need more control. It's a solid pick for busy QA teams.